I’m constantly shocked (and not shocked) at how companies are doing this and at the same time aren’t hosting the models themselves. Running deepseek on even the cloud is much cheaper, it’s your vms and your data. Or god forbid your own infra. Seems way safer, and yeah you have to maintain it, but it’s still your data.
Of course they fired everyone who knew how to stand up all of that so it probably isn’t even on their minds.
Modern business is addicted to outsourcing any aspect of business that’s not a “core competency.”
They pay Amazon or Microsoft run the data centers. They pay Accenture or Infosys for enterprise management applications, and so on.
They expected to pay their LLM vendors to build and maintain the LLMs, only to find out that they cost too much and don’t really work like they were promised.
Local Deepseek (or frankly, Eliza running on an 8086) is probably perfectly fine slop for 95% of your slop needs, but you’ve gotta have the biggest and shiniest slop. You clearly need a LLM powerful enough to invoke the apocalypse to polish that marketing budget spreadsheet, or you’ll be left behind.
Right, I’m even amazed that more businesses aren’t just using older gen models for slightly less ‘genius’ at a fraction of the cost. Maybe everyone’s buying hype, or maybe there’s a hiccup in enterprise scale contracts that I’m not familiar with.
One of our executives has been going off on how the cheapest model from the vendor is plenty good enough for anything the company might want to do. Hasn’t made the leap to just running it on-premise, but certainly already trying to still say “it’s really important” while “don’t spend so much money” at the same time.
For my vibing/slopping I completely agree. My local Qwen model can do 95% of the work. I keep Claude around only really for planning now, I plan in Claude then hand the plan over to the local models. Where before I had the Max subscription at 100/mo, now I’m down to the Pro at 20/mo, and may even drop that.
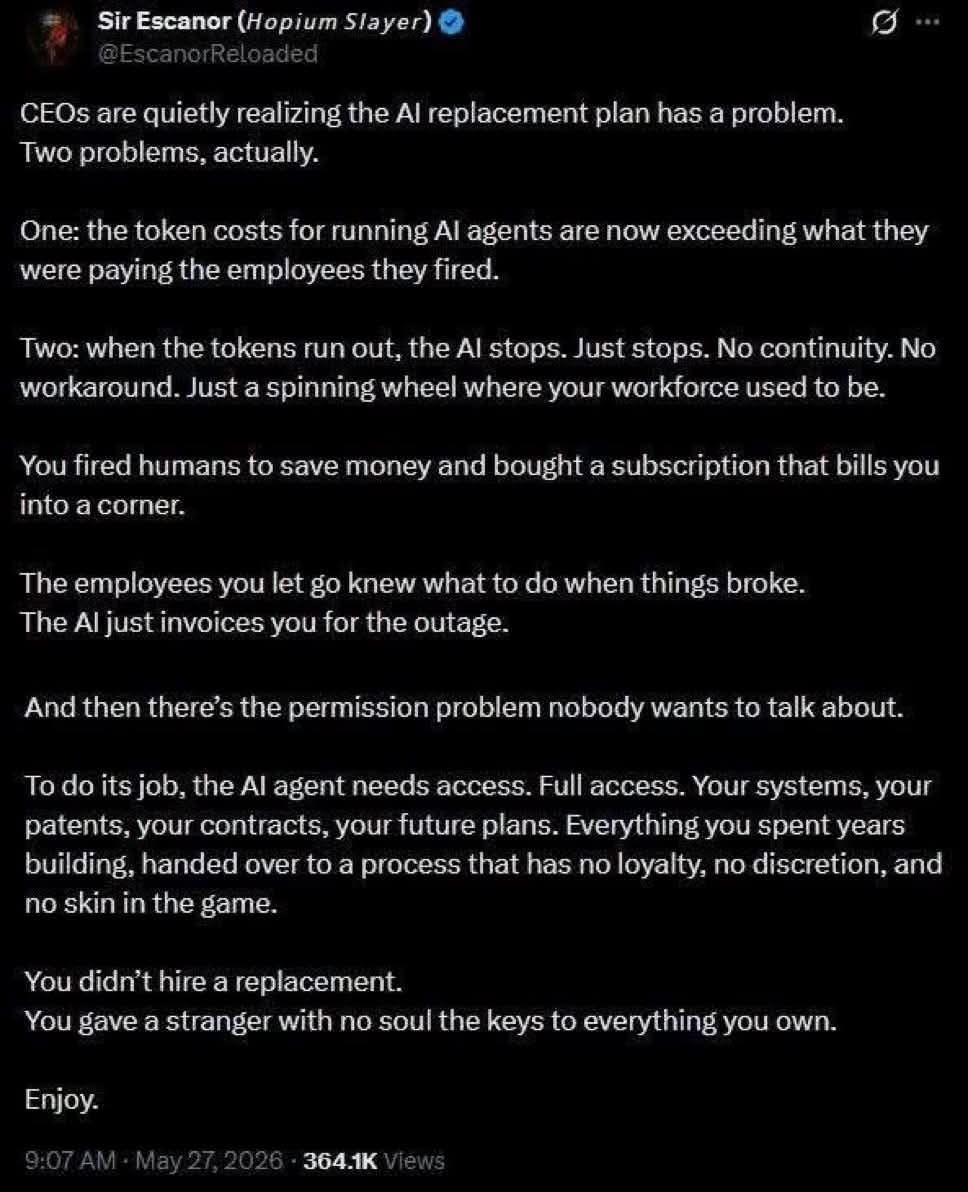
I’m constantly shocked (and not shocked) at how companies are doing this and at the same time aren’t hosting the models themselves. Running deepseek on even the cloud is much cheaper, it’s your vms and your data. Or god forbid your own infra. Seems way safer, and yeah you have to maintain it, but it’s still your data.
Of course they fired everyone who knew how to stand up all of that so it probably isn’t even on their minds.
The whole point of AI is to get everyone locked into the cloud, renting forever, without the knowledge to escape.
Modern business is addicted to outsourcing any aspect of business that’s not a “core competency.”
They pay Amazon or Microsoft run the data centers. They pay Accenture or Infosys for enterprise management applications, and so on.
They expected to pay their LLM vendors to build and maintain the LLMs, only to find out that they cost too much and don’t really work like they were promised.
The frontier vendors are great hype people.
Local Deepseek (or frankly, Eliza running on an 8086) is probably perfectly fine slop for 95% of your slop needs, but you’ve gotta have the biggest and shiniest slop. You clearly need a LLM powerful enough to invoke the apocalypse to polish that marketing budget spreadsheet, or you’ll be left behind.
Right, I’m even amazed that more businesses aren’t just using older gen models for slightly less ‘genius’ at a fraction of the cost. Maybe everyone’s buying hype, or maybe there’s a hiccup in enterprise scale contracts that I’m not familiar with.
One of our executives has been going off on how the cheapest model from the vendor is plenty good enough for anything the company might want to do. Hasn’t made the leap to just running it on-premise, but certainly already trying to still say “it’s really important” while “don’t spend so much money” at the same time.
For my vibing/slopping I completely agree. My local Qwen model can do 95% of the work. I keep Claude around only really for planning now, I plan in Claude then hand the plan over to the local models. Where before I had the Max subscription at 100/mo, now I’m down to the Pro at 20/mo, and may even drop that.