All this only applies to the cloudbased AI guys, like OpenAI and Anthropic. If you run your own open source models such as Kimi or GLM on your own or leased hardware - poof, problems gone.
Running your own model doesn’t solve every problem with LLMs, but it sure as hell does solve a ton of them, for way less money! Local models are great, gwen3.8 on my 3090 at home is slower, but often better than the pay to play Claude from work.
That’s what I run on my 7900 XTX and it’s about as good as Sonnet 5 that I use regularly at work. Zero reason to give Anthropic or OpenAI my money or data.
It maybe doesn’t solve ALL problems, but it solves the ones in this post: high token prices, running out of tokens shutting down the workflow, and handing over your sensitive data to corporates doing god knows what with it.
One of the better aspects of it is that it decentralizes power and cooling. When everyone has to juice up their own GPU and deal with the noise it makes in their office, you remove a lot of the problems related to the data center chewing up enormous amounts of electricity and water (or rather, if lots of people did that, it would target that problem). And that’s a lot more tolerable than giant data centers increasing the local temperature and chugging down the municipal water supply. Problem being that GPUs are now way too expensive. This will be a more approachable model when the bubble bursts (I hope).
No it isn’t. Those models are trained on the big models. They will not get better if the big providers go under. Sure, they’ll keep running, but half of the reason people are buying into all this AI nonsense is that it’s going to be much much better than it already is in the future.
It’s a process called distillation. One way of doing it is creating thousands of accounts to prompt a big flagship model, then use the output to pre-train their own model.
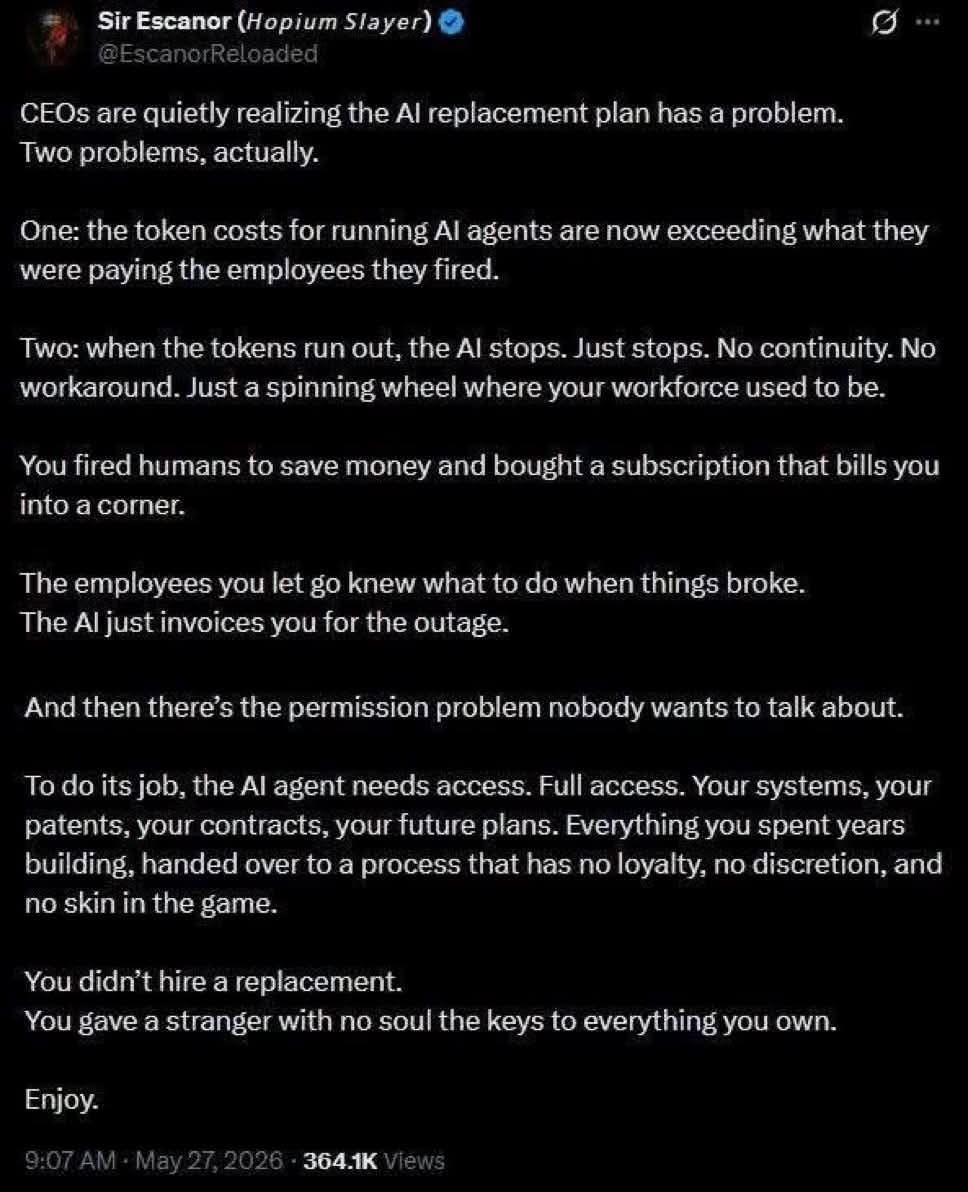
All this only applies to the cloudbased AI guys, like OpenAI and Anthropic. If you run your own open source models such as Kimi or GLM on your own or leased hardware - poof, problems gone.
I mean, not quite, but also yes.
Running your own model doesn’t solve every problem with LLMs, but it sure as hell does solve a ton of them, for way less money! Local models are great, gwen3.8 on my 3090 at home is slower, but often better than the pay to play Claude from work.
That’s what I run on my 7900 XTX and it’s about as good as Sonnet 5 that I use regularly at work. Zero reason to give Anthropic or OpenAI my money or data.
It maybe doesn’t solve ALL problems, but it solves the ones in this post: high token prices, running out of tokens shutting down the workflow, and handing over your sensitive data to corporates doing god knows what with it.
Exactly, that’s why I gave it the “No, but actually yes” preface.
One of the better aspects of it is that it decentralizes power and cooling. When everyone has to juice up their own GPU and deal with the noise it makes in their office, you remove a lot of the problems related to the data center chewing up enormous amounts of electricity and water (or rather, if lots of people did that, it would target that problem). And that’s a lot more tolerable than giant data centers increasing the local temperature and chugging down the municipal water supply. Problem being that GPUs are now way too expensive. This will be a more approachable model when the bubble bursts (I hope).
No it isn’t. Those models are trained on the big models. They will not get better if the big providers go under. Sure, they’ll keep running, but half of the reason people are buying into all this AI nonsense is that it’s going to be much much better than it already is in the future.
That’s just not true. They might steal from the American models, but they don’t depend on them.
They literally use them as base models for compression.
How do they do that exactly?
It’s a process called distillation. One way of doing it is creating thousands of accounts to prompt a big flagship model, then use the output to pre-train their own model.